






nginx 的故障转移机制在 kubernetes 中通过 service 的负载均衡和 endpoints 的动态更新来适配,核心做法是将 nginx 作为无状态服务部署,利用 k8s service 自动剔除不健康的 pod 并将流量转发至存活实例。具体实现时,需配置 health check 探针确保 k8s 能准确识别 pod 状态,并配合 ingress controller 处理外部流量的路由与重试。这样做的好处是无需手动维护节点列表,k8s 会自动管理后端 ip 的变化,从而实现高可用。
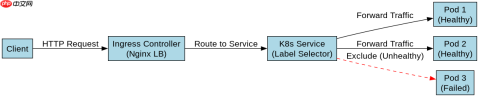
Kubernetes Service 如何替代 Nginx upstream 动态发现
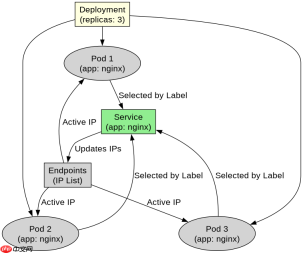
Kubernetes Service 通过 Label Selector 自动聚合匹配的 Pod IP,充当了 Nginx upstream 中动态后端列表的角色。当 Pod 重启或扩缩容时,Endpoints 控制器会实时更新 Service 的后端列表,Nginx Ingress Controller 监听这些变化并重新加载配置,从而将流量导向新的健康 Pod。这种机制消除了传统 Nginx 需要手动配置或依赖脚本更新 upstream 的复杂性。
apiVersion: v1
kind: Service
metadata:
  name: nginx-app
spec:
  selector:
    app: nginx
  ports:
  - port: 80
    targetPort: 80
---
apiVersion: apps/v1
kind: Deployment
metadata:
  name: nginx-deployment
spec:
  replicas: 3
  selector:
    matchLabels:
      app: nginx
  template:
    metadata:
      labels:
        app: nginx
    spec:
      containers:
      - name: nginx
        image: nginx:latest
        ports:
        - containerPort: 80
        readinessProbe:
          httpGet:
            path: /
            port: 80
          initialDelaySeconds: 5
          periodSeconds: 5
上述 YAML 定义了一个包含 3 个副本的 Nginx Deployment 和一个关联的 Service。Service 通过 label `app: nginx` 选择所有 Nginx Pod。Readiness Probe 确保只有成功响应 HTTP GET / 的 Pod 才会被加入 Endpoints,从而实现故障转移。当某个 Pod 失败时,它会被从 Endpoints 中移除,Service 不再向其发送流量,直到其恢复健康。
Ingress Controller 如何处理连接中断与重试
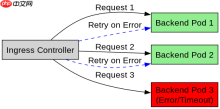
Ingress Controller(如 NGINX Ingress Controller)在 Kubernetes 中不仅负责暴露服务,还内置了类似 Nginx 的负载均衡和错误处理逻辑。它支持配置 `nginx.ingress.kubernetes.io/proxy-next-upstream` 等注解,模拟 Nginx 的 upstream 故障转移行为。当后端 Pod 返回 502、504 错误或连接超时时,Ingress Controller 可以自动将请求重试到其他健康后端,提升用户体验。

apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
  name: nginx-ingress
  annotations:
    nginx.ingress.kubernetes.io/proxy-next-upstream: "error timeout invalid_header http_500 http_502 http_503 http_504"
    nginx.ingress.kubernetes.io/proxy-next-upstream-tries: "3"
spec:
  rules:
  - host: example.com
    http:
      paths:
      - path: /
        pathType: Prefix
        backend:
          service:
            name: nginx-app
            port:
              number: 80
该 Ingress 资源配置了 `proxy-next-upstream` 注解,指定当遇到错误、超时或特定 HTTP 错误码时,Ingress Controller 应尝试重试其他后端。`proxy-next-upstream-tries` 设置为 3,表示最多重试 3 次。这相当于 Nginx 中的 `upstream` 故障转移策略,确保在单个 Pod 故障时,请求能被无缝转移到其他可用实例。
Pod 终止流程对 Nginx 优雅退出的影响
在 Kubernetes 中,Pod 删除时会先触发终止流程,此时 Service 会将该 Pod 从 Endpoints 中移除,但 Pod 进程仍在运行。如果 Nginx 未正确配置优雅退出,可能在终止期间仍接收流量导致请求失败。为确保故障转移平滑,需设置 `terminationGracePeriodSeconds` 并配置 Nginx 监听 SIGTERM 信号以完成当前请求后退出。
apiVersion: apps/v1
kind: Deployment
metadata:
  name: nginx-deployment
spec:
  template:
    spec:
      terminationGracePeriodSeconds: 30
      containers:
      - name: nginx
        image: nginx:latest
        lifecycle:
          preStop:
            exec:
              command: ["/bin/sh", "-c", "sleep 10"]
此配置将 `terminationGracePeriodSeconds` 设为 30 秒,并在 `preStop` 钩子中插入 10 秒延迟。这给 Nginx 足够时间处理完正在进行的请求,同时让 K8s 有充足时间将流量切换至其他 Pod。若未配置此延迟,Nginx 可能立即退出,导致部分请求丢失,影响故障转移效果。





